
When Context Hinders AI: Why Must an Agent Also Know What to Forget?
Date: October 2, 2026
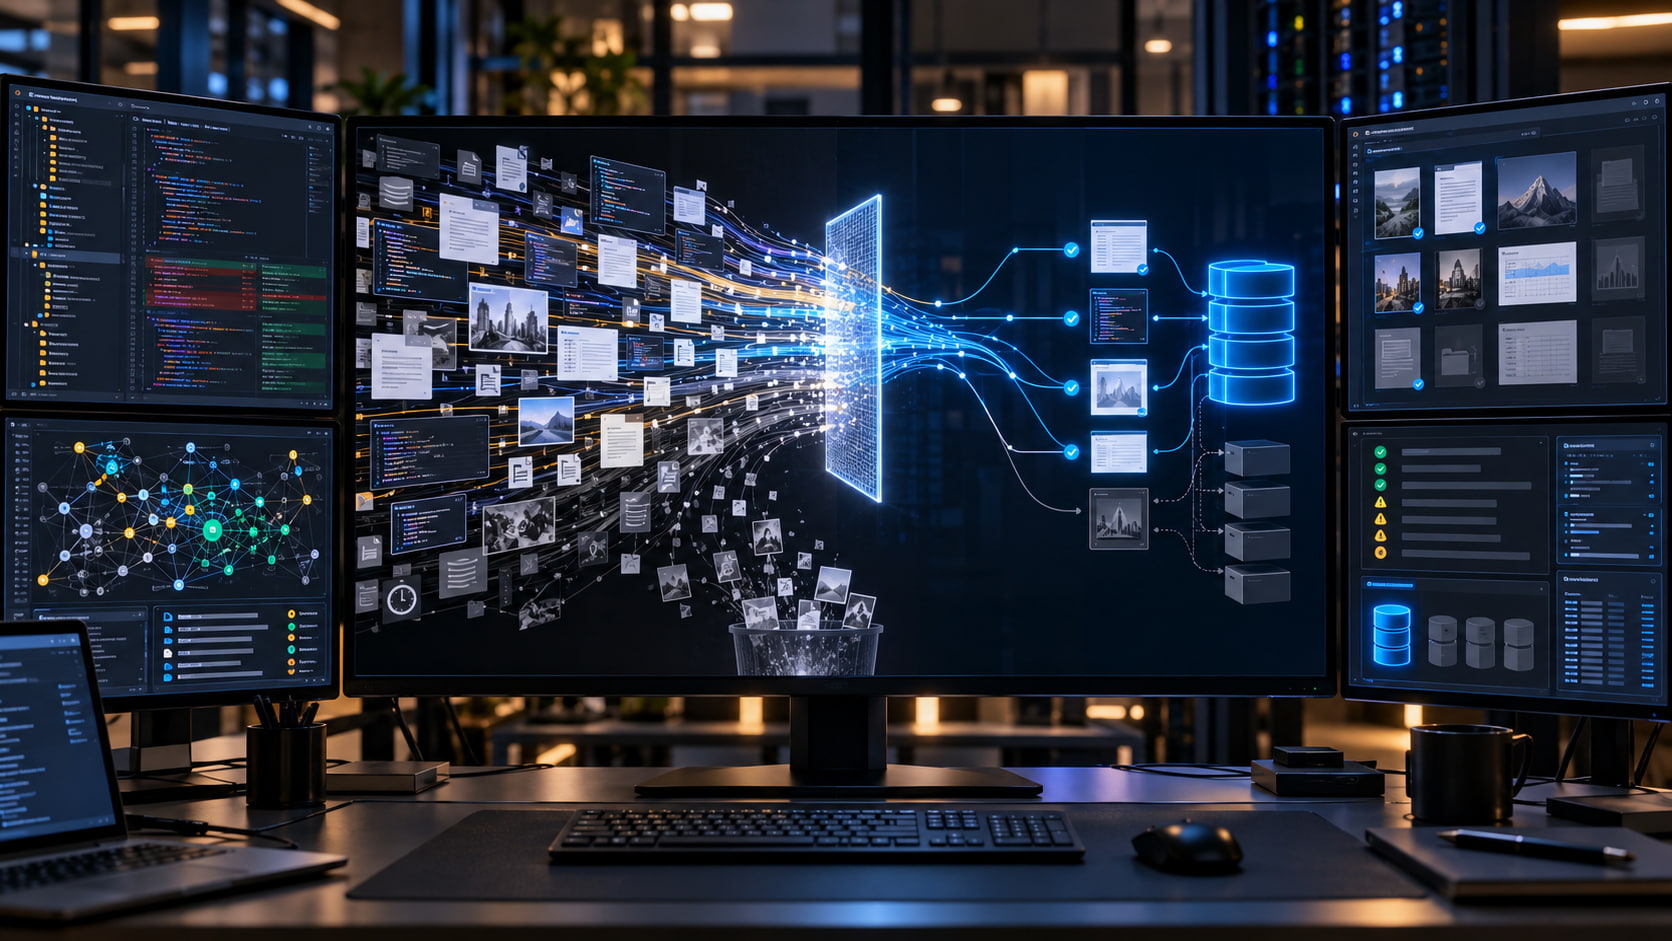
When an AI Agent works on a software task, context is one of its most important resources. It may include the user’s request, project files, change history, team instructions, system architecture, and conclusions drawn from previous tasks.
At first glance, it may seem that the more information an agent receives, the better the result will be. If AI knows more parts of the repository and retains more history, it should be able to make more accurate decisions.
But the quantity of context is not equal to the quality of context.
Outdated, irrelevant, or contradictory information can lead the agent away from the problem it needs to solve. Instead of helping, excessive history can make the process more expensive, slower, and less focused.
GitHub has announced that its researchers have built a benchmark using sequences of real pull requests and analyzed the impact of accumulated context. The topic, which will be presented at GitHub Universe 2026, focuses precisely on what an agent should remember and what information it should leave behind.
This shifts the question from “How much context can AI retain?” to a more important one: “Which context is still valid for the current task?”
Context and memory are not the same thing
Context is the information an agent uses during a specific task. It may include the prompt, open files, search results, tool outputs, and previous responses.
Memory, on the other hand, is information stored for use in future tasks.
An agent may discover, for example, that an API version must remain consistent across client code, the server, and the documentation. This is a conclusion that may also be useful during a future change.
If this information is stored as memory, another agent can use it later to verify whether every relevant location has been updated.
But not every piece of information that appears during a task should be retained.
A file opened by chance, a development branch that was never merged into the main codebase, or a temporary solution should not automatically be treated as long-term project knowledge.
Therefore, AI context management requires a clear distinction between temporary information and knowledge worth preserving.
More information can distract the agent from the problem
During a code review, the agent must determine whether the proposed change creates a real problem. To do this, it usually needs to begin with the diff and search only for code related to the review question.
If it instead begins exploring the repository broadly, every search result and every file it reads becomes part of its working context.
This information continues to accompany the agent’s reasoning even when it is no longer useful. As a result, the agent may spend more resources analyzing irrelevant material and lose focus on the change it needs to review.
GitHub reported a case in which better code-exploration tools initially made Copilot code review worse. The agent searched too broadly, read more code than necessary, and accumulated context throughout the process. After the instructions were adapted to guide it to begin with the diff and search for limited evidence, the average review cost was reduced by approximately 20% while preserving the same quality.
This shows that the ability to find more information is not always an improvement. The value lies in finding the right information.
Context must match the task
An agent implementing a function and an agent reviewing a pull request do not have the same context requirements.
The agent implementing a change may need to understand the architecture of a module, its dependencies on other components, and the way the functionality is tested.
The code review agent must be more focused. It should begin with the specific change, formulate precise questions, and search only for the evidence needed to confirm or dismiss a problem.
Even when both agents use the same tools, the way they collect context should be different.
This means that context management cannot be solved with a universal rule. Each role should have clear boundaries, search strategies, and criteria for the information it may load.
An agent should not read the entire repository simply because it can. It should read the part connected to the decision it is trying to make.
Information that is correct today may be wrong tomorrow
Software changes continuously.
A rule identified in one project branch may be replaced before that branch is merged. A coding convention may change. A component may be removed, while a dependency may be replaced with another solution.
If AI stores a conclusion without checking its source, it may continue using it even after the information is no longer valid.
The problem is not only that the memory is old. The problem is that it may still appear convincing.
A conclusion stored by AI may be clearly written and sound technically correct, even though the current code no longer supports it.
For this reason, memory should not be treated as an unchangeable truth. It should be treated as information that requires verification against the current state of the system.
Memory should also preserve its source
One way to limit the use of inaccurate memories is to associate every stored piece of information with the reference that supports it.
In the system described by GitHub, memories are stored with citations to specific locations in the code. Before using a memory, the agent checks in real time whether the referenced files and sections still support that information.
If the code contradicts the memory or the location no longer exists, the agent should not use the old conclusion. It can correct it based on the new evidence.
This approach moves verification to the moment of use. Instead of attempting to continuously clean the entire memory store, the system checks the information when it becomes necessary for a specific task.
GitHub reports that, in its tests, using verified memory produced a 3% increase in precision and a 4% increase in recall during code review.
Memory can therefore improve the outcome, but only when the information is stored and used with verification mechanisms.
Forgetting is part of the system’s intelligence
Forgetting is usually viewed as a limitation. In AI systems, it can be an important control mechanism.
A memory that has not been used for a long period may no longer be relevant. Information that cannot be verified should be removed. A conclusion associated with an abandoned branch should not continue influencing new tasks.
Copilot Memory restricts memories to the repository level and checks them against the current codebase before use. GitHub also sets an automatic 28-day expiration period for memories, while repository owners can review and delete them.
This shows that forgetting should not happen randomly. It can be designed through expiration periods, source verification, and administrative controls.
A good memory system is not one that retains everything. It is one that retains useful information for as long as it remains valid.
Context should be selected, not loaded in full
When beginning a new task, the agent may have access to conversation histories, documentation, repository memories, files, and results from previous processes.
Loading all this data into the prompt is not necessarily the best strategy.
The system should determine which information relates to the current objective. A task involving authentication may need security rules and the relevant dependencies, but not the history of an old change to the graphical interface.
This requires mechanisms for searching, ranking, and filtering memory. Information can be evaluated according to its relevance to the question, the time it was created, the reliability of its source, and its validity in the current code.
The objective is not to fill the context window. The objective is to provide the agent with the minimum information it needs to make an accurate decision.
Shared memory can distribute both knowledge and errors
When several AI Agents work on the same project, memory can allow knowledge discovered by one agent to be used by others.
A code review agent may identify an important convention. A coding agent can apply it while creating a new service, while a terminal agent can use it when diagnosing a problem.
This can reduce the need to explain the same context to each agent.
But shared memory also creates a risk. If incorrect information is stored and not verified, it may spread across several processes. A single error can affect implementation, code review, and diagnostics.
Therefore, sharing memory should be accompanied by sharing evidence. Agents should not inherit only a conclusion, but also the ability to verify its source.
Context management becomes part of the architecture
In traditional systems, context may simply be part of the prompt. When AI Agents begin working in long-running processes, it becomes an architectural component.
The system must define where memory is stored, who may create it, which agents may read it, how long it remains active, and how its validity is verified.
It should also be possible to understand which information influenced an agent’s decision.
If AI proposes a change based on a previous memory, the team should be able to see what that memory contained, which code it was derived from, and whether it was verified before use.
This makes context management part of system auditing, security, and accountability.
AI must know not only what it knows, but also why it knows it
For Soft&Solution Group, an AI Agent’s memory should not be treated as an unlimited repository of information.
Its value depends on the ability to connect every conclusion to a source, verify it against the system’s current state, and remove it when it is no longer valid.
As Ermal Beqiri, founder of Soft&Solution Group, states:
“An AI Agent does not become more accurate simply because it retains more information. It must distinguish what is relevant to the current task, verify whether the memory continues to be supported by the system, and leave behind context that is no longer valid. Intelligence lies not only in what the agent remembers, but also in how it chooses what to use.”
AI Agents are moving from isolated conversations toward processes that can continue across several tasks, tools, and stages of development. In this model, memory can preserve project knowledge and make work more consistent.
But uncontrolled memory can create noise, increase costs, and spread outdated information.
For this reason, AI context management should not focus on retaining everything. It should define what is worth preserving, how it is verified, and when it should be forgotten.
The most useful AI is not the one that remembers everything. It is the one that uses the right information, at the right time, and for the right reason.